Attention is a small amount of linear algebra wrapped around one softmax. It is also the part of a transformer that people most often describe with metaphors ("the model looks at the relevant words") instead of equations. This post implements it in NumPy, builds a toy example where the weights are chosen by hand so the heatmaps can be read without guessing, and measures why the
Scaled dot-product attention
Given queries
where the softmax is applied row by row and
- The output is permutation-equivariant in the keys and values: attention has no notion of order unless the inputs carry positional information.
- The weights sum to one per query, so attention averages values; it cannot amplify a single value beyond its own magnitude.
- The cost is
import numpy as np

def softmax(x, axis=-1):
    x = x - x.max(axis=axis, keepdims=True)            # shift for numerical stability
    e = np.exp(x)
    return e / e.sum(axis=axis, keepdims=True)

def attention(Q, K, V, mask=None):
    d = Q.shape[-1]
    S = Q @ np.swapaxes(K, -1, -2) / np.sqrt(d)        # (..., T_q, T_k) scores
    if mask is not None:
        S = np.where(mask, S, -1e9)                    # False -> effectively -inf
    A = softmax(S)
    return A @ V, A                                    # output and the weights themselves
WARNING
Use a large negative finite number for masked positions, not
-np.inf. If an entire row is masked (it happens with padding masks on empty sequences),exp(-inf - (-inf))producesnanand the loss silently becomesnanseveral layers later. Thex - x.max()shift in the softmax is equally non-negotiable: without it,expoverflows for logits above about 709 in double precision and far earlier in float16.
Masks
A causal (decoder) mask forbids query np.tril(np.ones((T, T), bool)). A padding mask forbids attending to positions that are not real tokens, and is broadcast across queries. Both are combined with logical AND before being passed in. Because the mask is applied to the scores before the softmax, the forbidden positions receive exactly zero weight and the remaining weights still sum to one.
Multi-head attention
One attention head computes one weighting pattern per query. Multi-head attention projects the input into
with
def split_heads(X, h):                                 # (T, d_model) -> (h, T, d_model / h)
    T, d = X.shape
    return X.reshape(T, h, d // h).transpose(1, 0, 2)

def merge_heads(Y):                                    # (h, T, d_k) -> (T, h * d_k)
    h, T, dk = Y.shape
    return Y.transpose(1, 0, 2).reshape(T, h * dk)

def multihead(X, Wq, Wk, Wv, Wo, h, mask=None):
    Q, K, V = (split_heads(X @ W, h) for W in (Wq, Wk, Wv))
    Y, A = attention(Q, K, V, mask)                    # broadcasting over the head axis
    return merge_heads(Y) @ Wo, A                      # A has shape (h, T, T)
A toy sequence with hand-built heads
Learned attention weights are hard to interpret because the projections are opaque. To see what the mechanism can do, the toy below constructs the projections by hand. Each token is represented by a one-hot word identity concatenated with a one-hot position, and two heads are given different jobs:
- Head 1 (content):
- Head 2 (position):
tokens = "the cat sat on the mat because the cat was tired".split()
T, vocab = len(tokens), sorted(set(tokens))
ids = np.array([vocab.index(t) for t in tokens])
h, dk = 2, 12
X = np.zeros((T, h * dk))
X[np.arange(T), ids] = 1.0                       # word one-hot in head-1 dims
X[np.arange(T), dk + np.arange(T)] = 1.0         # position one-hot in head-2 dims

scale = 14.0                                     # sharpness of the match
Wq, Wk = np.zeros((h * dk, h * dk)), np.zeros((h * dk, h * dk))
Wq[:len(vocab), :len(vocab)] = scale * np.eye(len(vocab))
Wk[:len(vocab), :len(vocab)] = np.eye(len(vocab))
M = np.eye(T, k=-1)                              # position i -> one-hot at i - 1
Wq[dk:dk + T, dk:dk + T] = scale * M
Wk[dk:dk + T, dk:dk + T] = np.eye(T)
causal = np.tril(np.ones((T, T), bool))
Y, A = multihead(X, Wq, Wk, np.eye(h * dk), np.eye(h * dk), h, causal)

The second occurrence of cat (position 8) gets weights
Why divide by the square root of d
If the components of
The one-line variance calculation
For independent
Without the scaling the logits grow like
| d_k | std of | std of | Entropy, unscaled (nats) | Entropy, scaled (nats) |
|---|---|---|---|---|
| 4 | 2.00 | 1.00 | 1.75 | 2.37 |
| 16 | 4.05 | 1.01 | 0.89 | 2.36 |
| 64 | 8.04 | 1.00 | 0.41 | 2.35 |
| 256 | 16.03 | 1.00 | 0.19 | 2.35 |
| 1024 | 31.95 | 1.00 | 0.09 | 2.36 |
The maximum possible entropy over 16 keys is

What the implementation leaves out
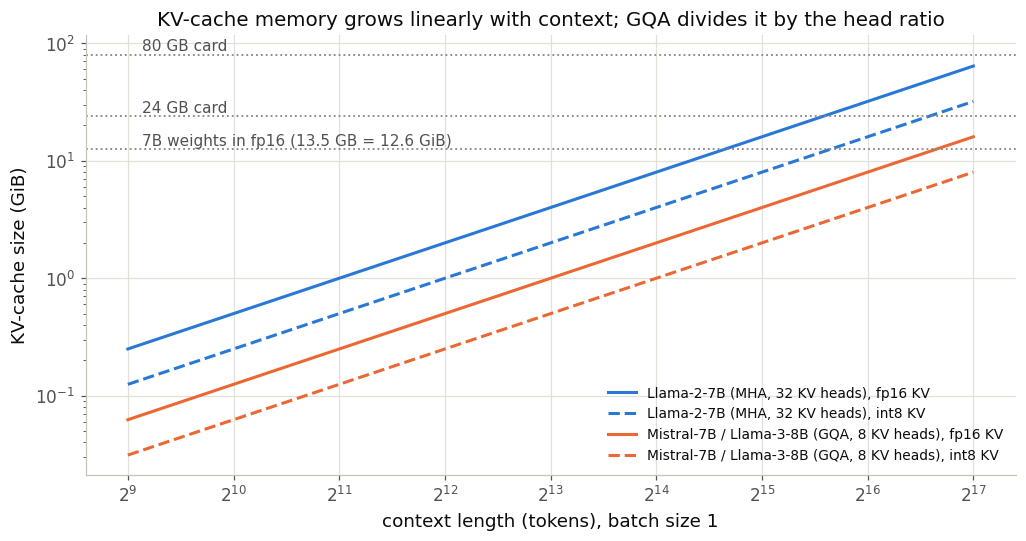
A production attention layer adds dropout on the weights, a key/value cache for autoregressive decoding, grouped or multi-query sharing of
Further reading
- Vaswani et al. (2017), Attention is all you need: https://arxiv.org/abs/1706.03762
- Bahdanau, Cho and Bengio (2014), Neural machine translation by jointly learning to align and translate, the additive attention that preceded it: https://arxiv.org/abs/1409.0473
- Jay Alammar, The Illustrated Transformer: https://jalammar.github.io/illustrated-transformer/
- Harvard NLP, The Annotated Transformer, a line-by-line implementation: https://nlp.seas.harvard.edu/annotated-transformer/
- Dao et al. (2022), FlashAttention: fast and memory-efficient exact attention with IO-awareness: https://arxiv.org/abs/2205.14135
- PyTorch documentation for
scaled_dot_product_attention, the fused primitive: https://docs.pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html