Transformers
Posts with this tag
Posts
-
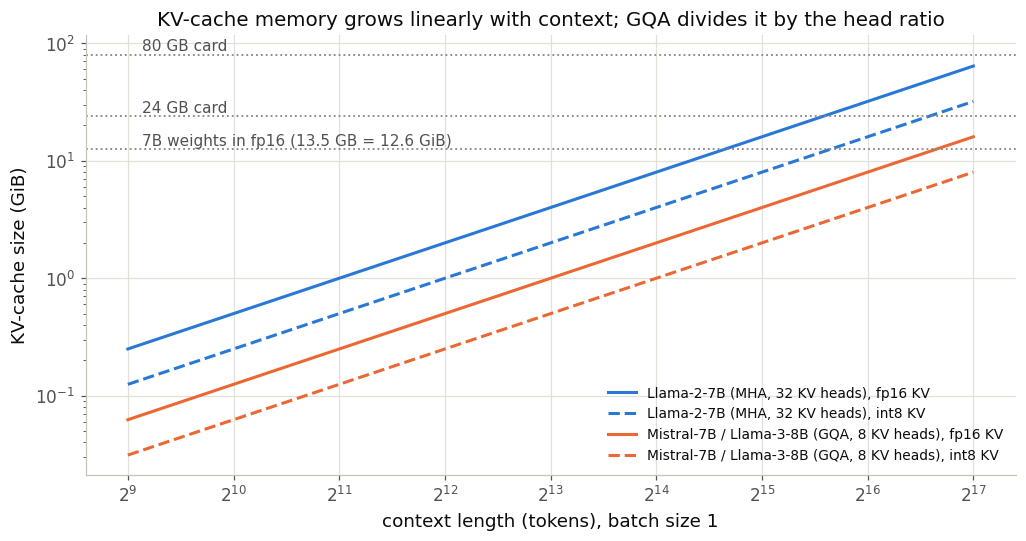
What Happens at Generation Time: KV Cache, RoPE and Sampling
The decode loop of a decoder-only transformer explained from the memory up, with KV-cache arithmetic for 7B-class models, a NumPy check of rotary embeddings, and temperature and top-p sampling.
-
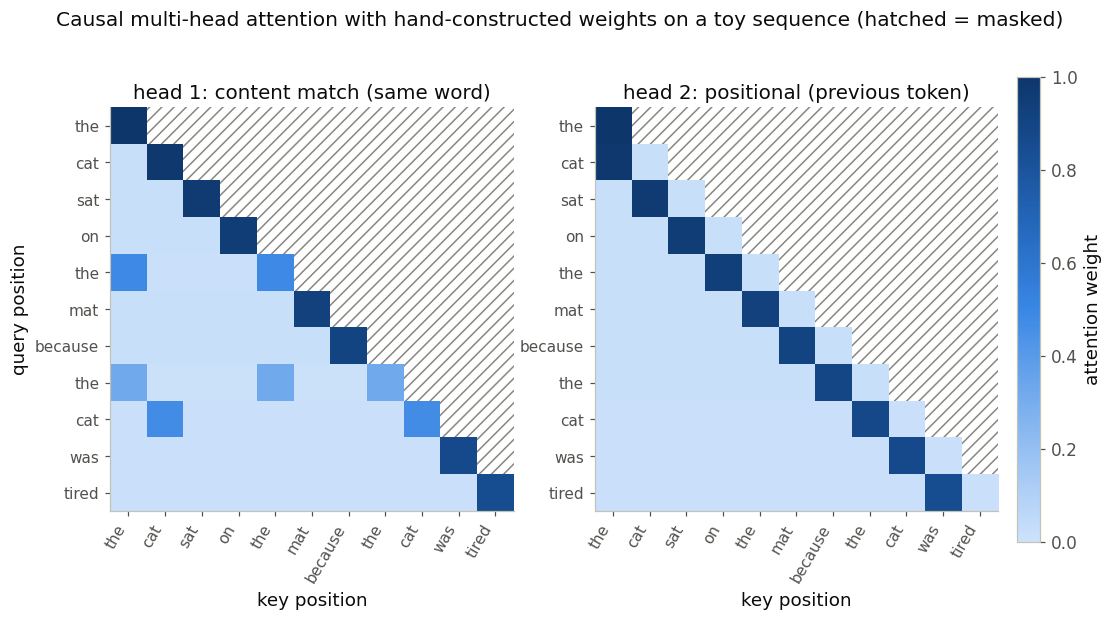
Attention in NumPy: Scaled Dot-Product, Masks and Multiple Heads
Implementing scaled dot-product and multi-head attention from scratch, explaining the square-root scaling with a measurement, and reading attention heatmaps on a toy sequence.