Vectorization
Posts with this tag
Posts
-
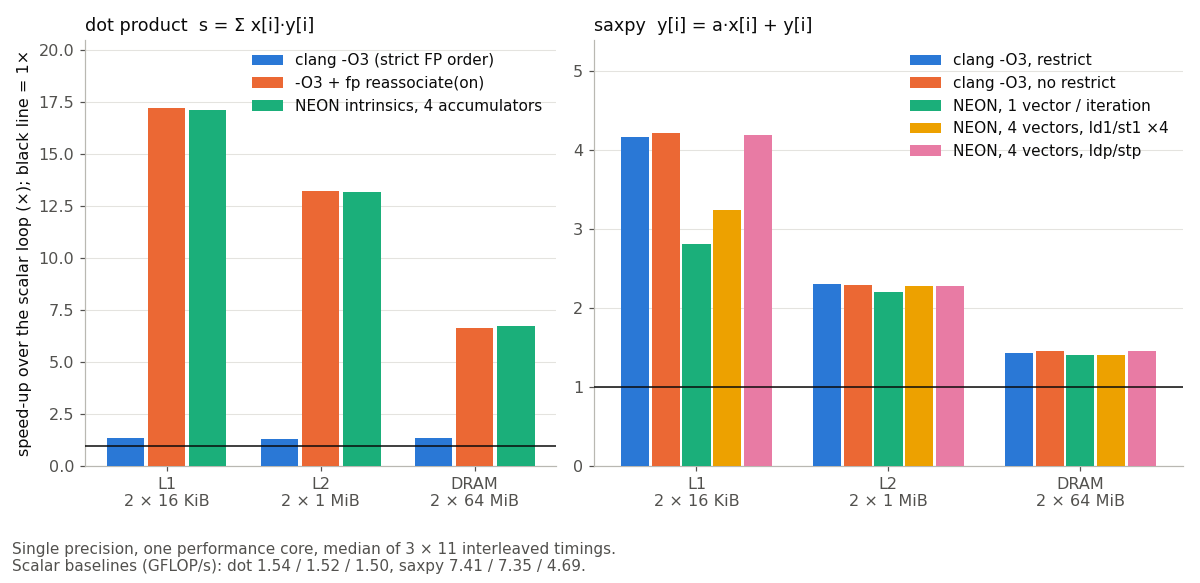
SIMD on the Laptop: NEON Intrinsics, Auto-Vectorisation and the Loop That Would Not Vectorise
Dot product and saxpy in single precision, scalar vs auto-vectorised vs NEON intrinsics, measured from L1, L2 and DRAM on an Apple-silicon laptop, with the assembly and remarks that explain them.
-
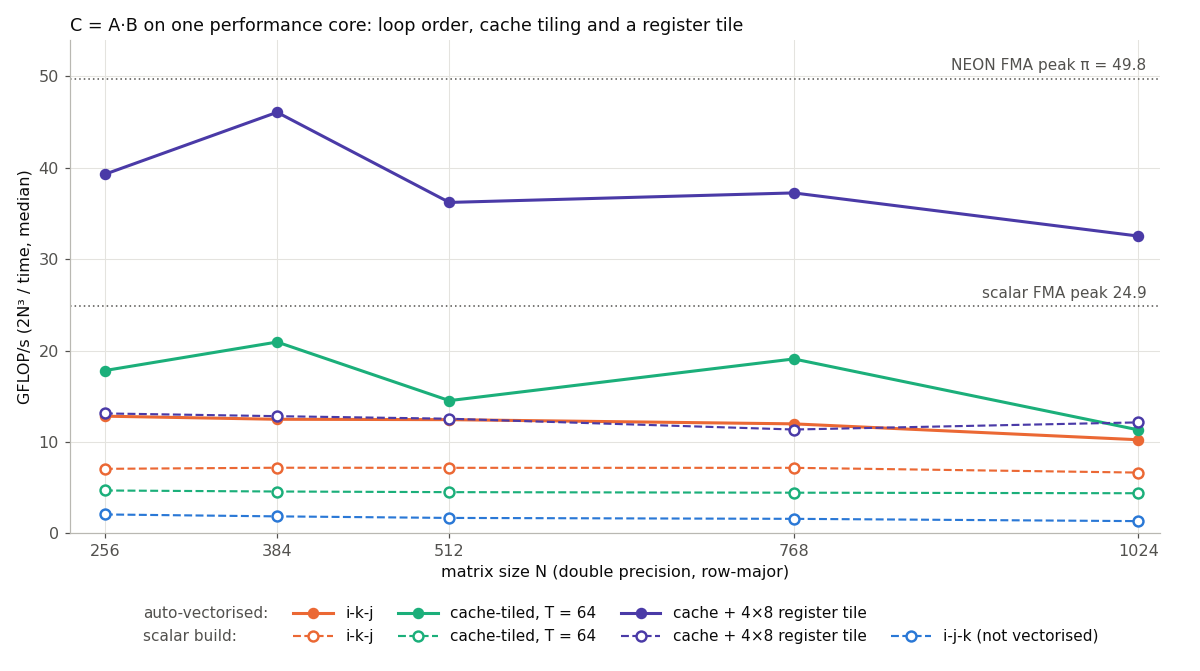
Cache-Aware Matrix Multiplication: Loop Order, Tiles and the Register Block That Did the Work
Naive, interchanged, cache-tiled and register-tiled DGEMM in plain C, auto-vectorised by clang, measured for N = 256 to 1024 on an Apple-silicon core and placed on the roofline.