CUDA
Posts with this tag
Posts
-
GPU Memory Hierarchy and Occupancy: Why a Tiled Kernel Is Just Cache Blocking by Hand
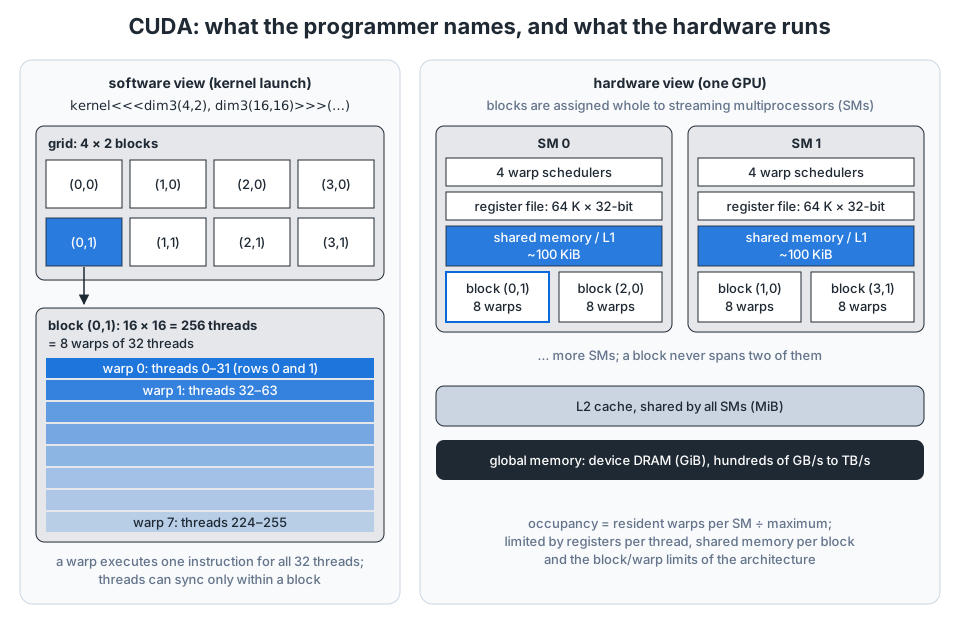
The CUDA execution model, global versus shared memory, coalescing, bank conflicts and occupancy, with a tiled matrix multiplication and a block reduction written out in full and traced back to the cache ideas of the CPU posts.