HPC
Posts in this category
Posts
-
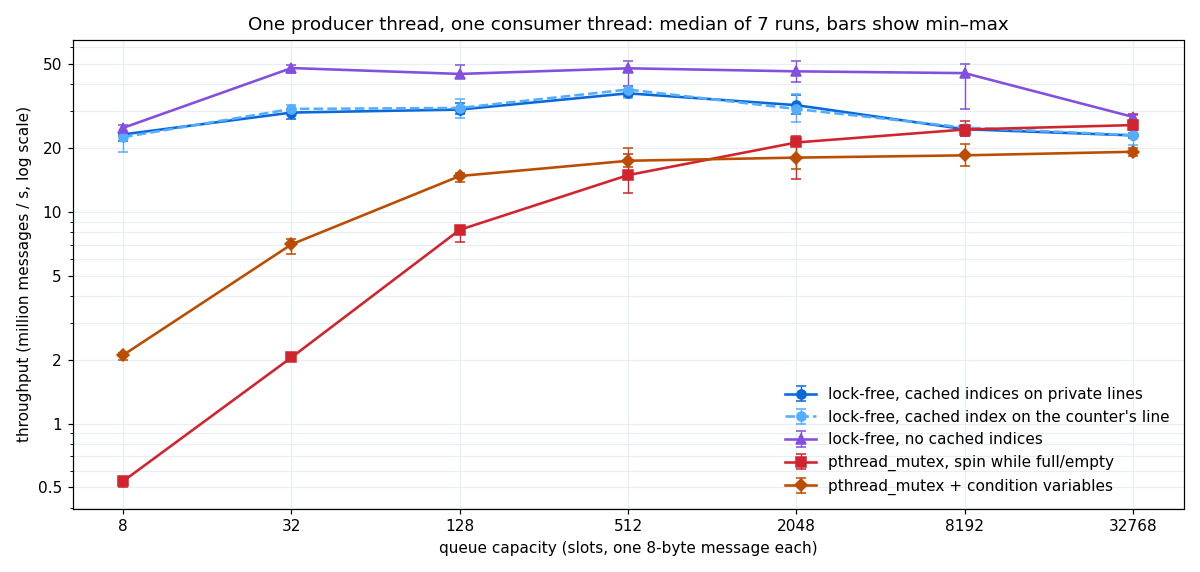
Lock-Free Queues and Memory Ordering: An SPSC Ring Buffer Measured Against a Mutex
A single-producer single-consumer ring buffer in C11 atomics, the happens-before argument that makes acquire/release enough, ABA and MPMC caveats, and a measured comparison with pthread_mutex queues.
-
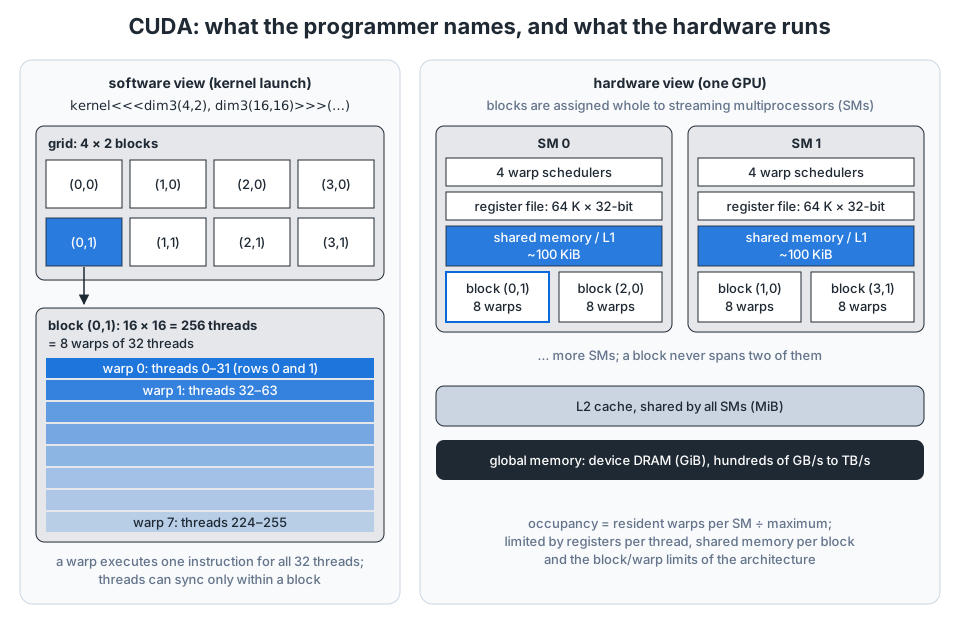
GPU Memory Hierarchy and Occupancy: Why a Tiled Kernel Is Just Cache Blocking by Hand
The CUDA execution model, global versus shared memory, coalescing, bank conflicts and occupancy, with a tiled matrix multiplication and a block reduction written out in full and traced back to the cache ideas of the CPU posts.
-
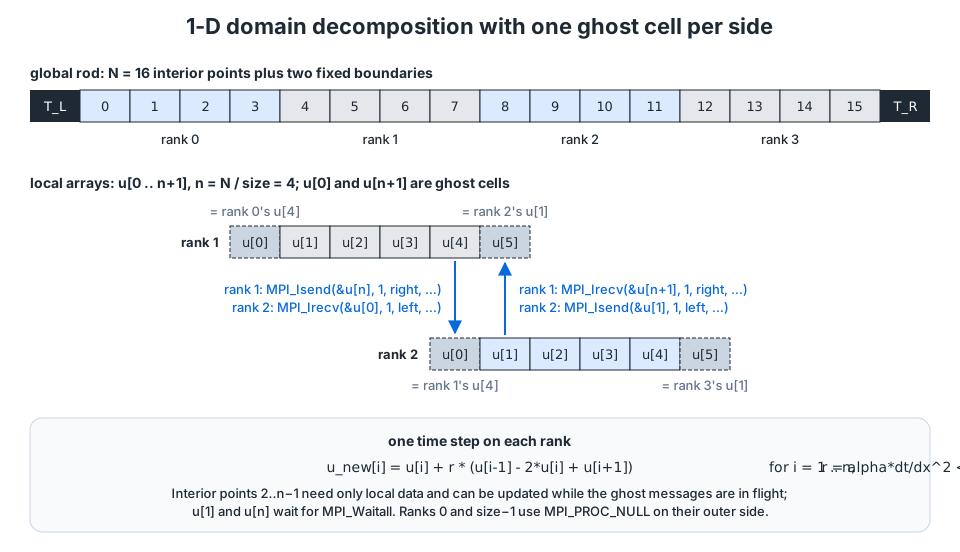
MPI from Zero: Ranks, Messages and a 1-D Heat Equation with Halo Exchange
What an MPI program is, how point-to-point and collective communication differ, the deadlock everyone writes once, and a complete heat-equation solver with ghost cells and non-blocking overlap, compiled and checked against Open MPI on a single laptop.
-
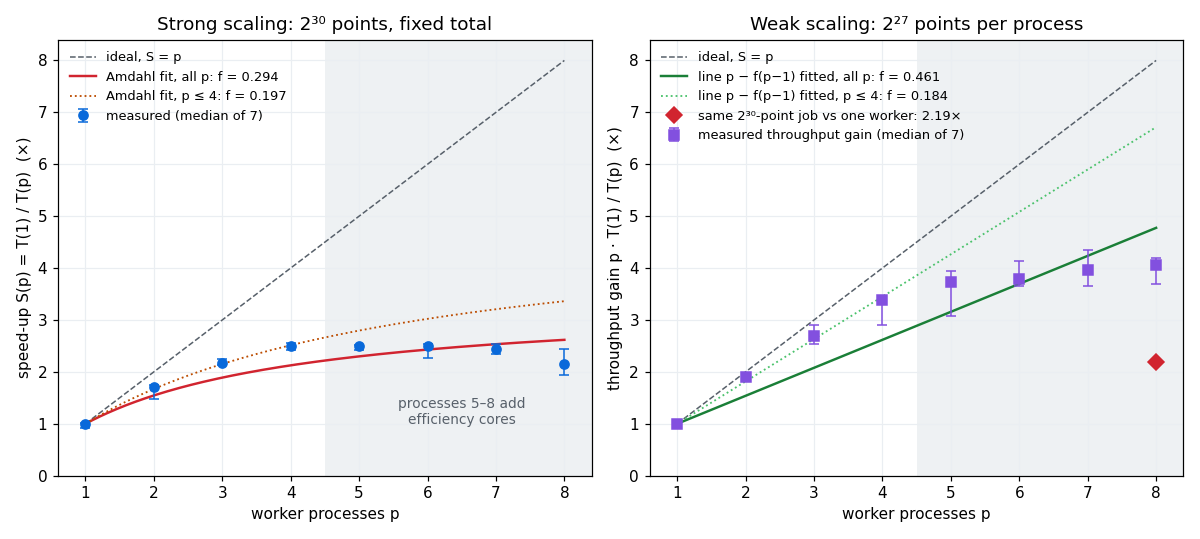
Amdahl, Gustafson and a Real Scaling Curve: Fitting the Serial Fraction of a Python Pool
Strong and weak scaling of a Python multiprocessing integration on an eight-core laptop, a fit of Amdahl's law, why a weak-scaling speed-up needs its baseline, and where the overhead comes from.
-
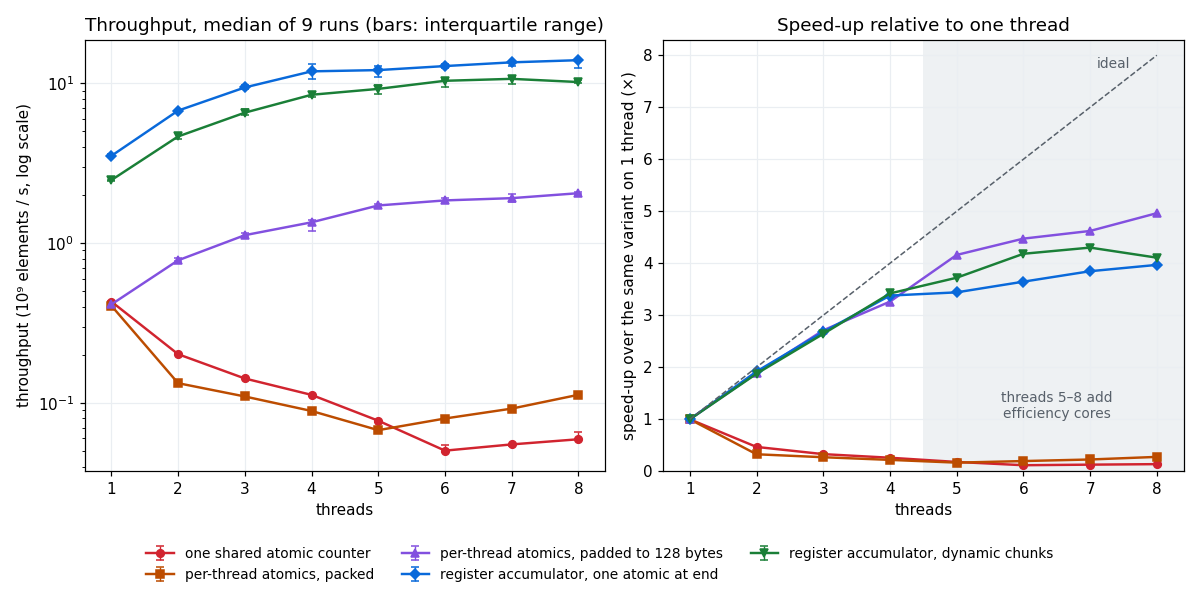
Threads, Reductions and False Sharing: Five Ways to Add Up Numbers in Parallel
A pthreads reduction measured five ways on an eight-core laptop: one shared atomic, packed per-thread counters, padded per-thread counters, register accumulators, and dynamic chunking, with a short primer on the C11 memory model that makes the fast version correct.
-
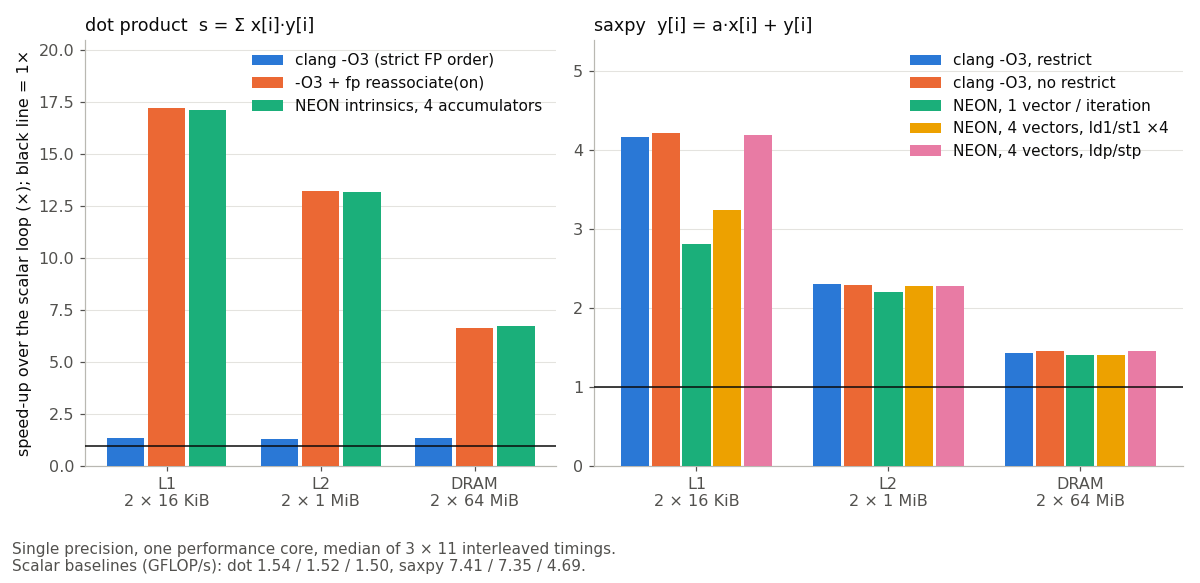
SIMD on the Laptop: NEON Intrinsics, Auto-Vectorisation and the Loop That Would Not Vectorise
Dot product and saxpy in single precision, scalar vs auto-vectorised vs NEON intrinsics, measured from L1, L2 and DRAM on an Apple-silicon laptop, with the assembly and remarks that explain them.
-
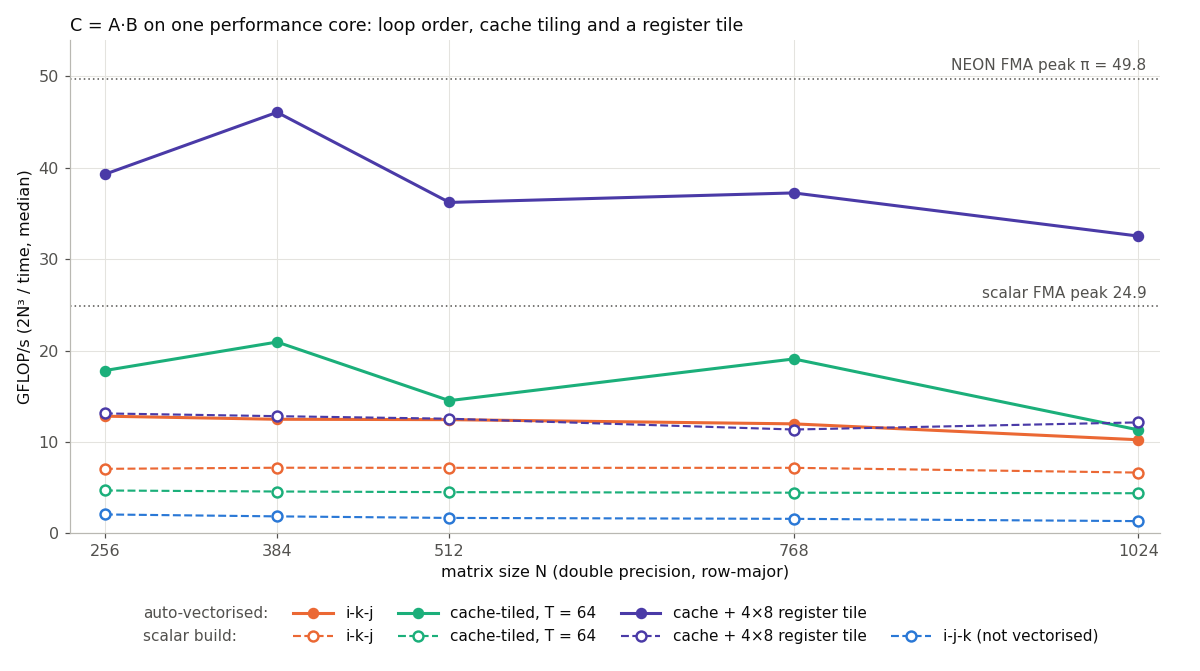
Cache-Aware Matrix Multiplication: Loop Order, Tiles and the Register Block That Did the Work
Naive, interchanged, cache-tiled and register-tiled DGEMM in plain C, auto-vectorised by clang, measured for N = 256 to 1024 on an Apple-silicon core and placed on the roofline.
-
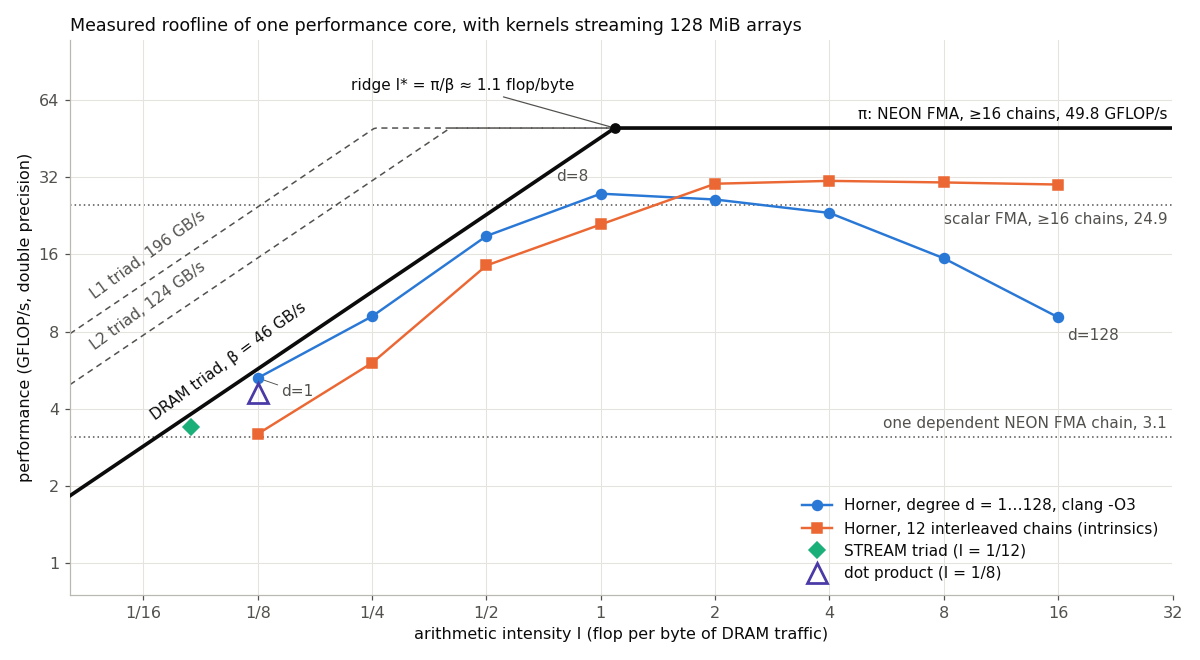
The Roofline Model on a Laptop: Measuring the Bandwidth Slope, the FMA Ceiling and the Ridge
Arithmetic intensity and the bound P = min(π, βI), with the bandwidth roof and FMA ceilings measured in C on one core of an Apple-silicon laptop, and a kernel walked across the ridge.